
Unveiling the Curiosities of AI: How fEmbedding Models Deviate from Physical Reality
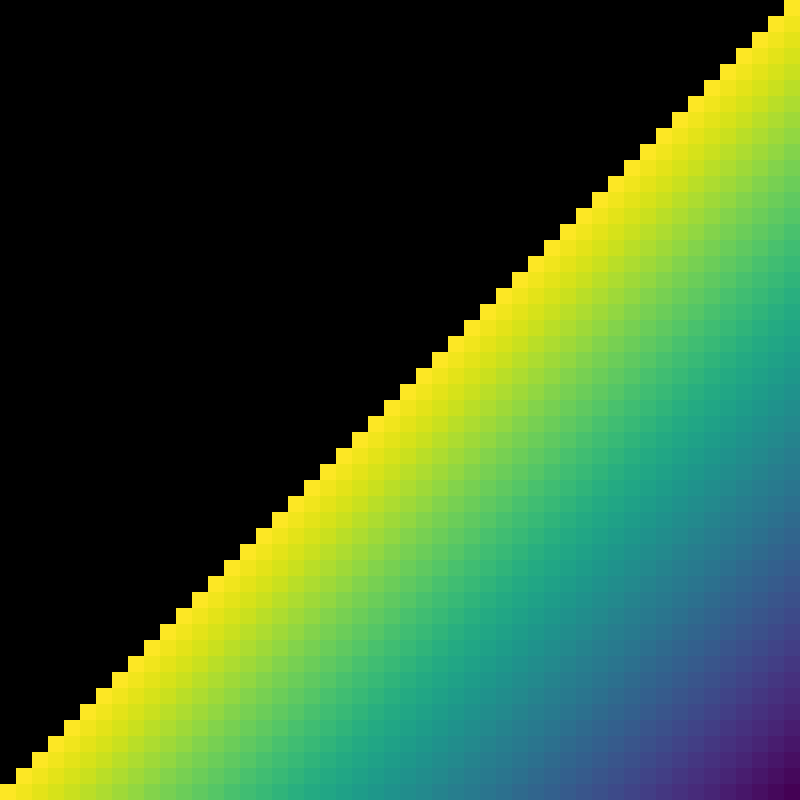
In a groundbreaking study, researchers Juri Opitz and Andrianos Michail from the University of Zurich delve deep into the intricacies of embedding models, probing their alignment—or lack thereof—with physical measurements. Titled fEmbedding Models Measure in Peculiar Ways, the paper reveals striking insights about how these models interpret semantic similarity, particularly through the lens of physical metrics like mass, distance, time, and volume.
The Core Question: How Well Do Embeddings Reflect Physical Measurements?
At the heart of the research lies a compelling question: to what extent do embeddings in AI models accurately reflect the structured relationships found in our physical world? For example, the researchers explore whether "1 meter" is closer to "100 centimeters" than to "15 kilometers" in an embedding space, highlighting the expectation that synonymous measures should exhibit a closer distance in vector representation. However, the findings indicate a concerning divergence from this expectation.
Peculiar Measurement Patterns Discovered
Through the analysis of 24 different embedding models, the researchers observed numerous peculiar patterns that defy the anticipated alignment with physical measures. Contrary to the ideal linear configuration where similarity should decrease smoothly with increasing physical distance, the study revealed erratic arrangements. Notably, the results showed pronounced non-monotonic artifacts, such as alternating bands of similarity, which suggested that superficial string similarity often supplants true semantic or quantitative relationships.
Misalignment Roots: Lexical Overlap Over Physical Meaning
One of the pivotal discoveries was that the embedding similarity of physical measurements correlates more strongly with lexical similarities—how words look or are structured—rather than their numerical distance or meaning. This implies that models are perhaps more focused on the superficial characteristics of text rather than on the underlying quantities those texts represent, leading to potentially misleading interpretations in contexts where accuracy is crucial.
Implications for AI and Future Research
The implications of these findings are profound. As embedding models become increasingly integrated into systems for scientific reasoning, engineering, and other quantitative disciplines, the need for a more faithful representation of physical measurements becomes apparent. This research not only calls into question the current capabilities of AI models but also suggests a roadmap for future innovations: embedding models must evolve to better capture and reflect quantitative semantics.
Ultimately, the authors hope this work will contribute to refining the metrics by which we evaluate AI systems, ensuring they align more closely with the nuances of our physical reality—not just as strings of text but as representations of true quantities and relationships.
For AI researchers and practitioners alike, understanding these dynamics will be crucial in developing tools capable of meaningful semantic comprehension and functionality.


